-
 HPE ProLiant DL380A Gen12: The Ultimate 4U Dual-Socket AI Server with Intel® Xeon® 6 CPUs and 10 Double-Width GPU Support
USD80,000
-
 Aetina MegaEdge AIP-KQ67 (PCIe AI Workstation)
USD25,600
-
 NVIDIA H100 80GB PCIe Tensor Core GPU
USD51,200Original price was: USD51,200.USD49,600Current price is: USD49,600. -
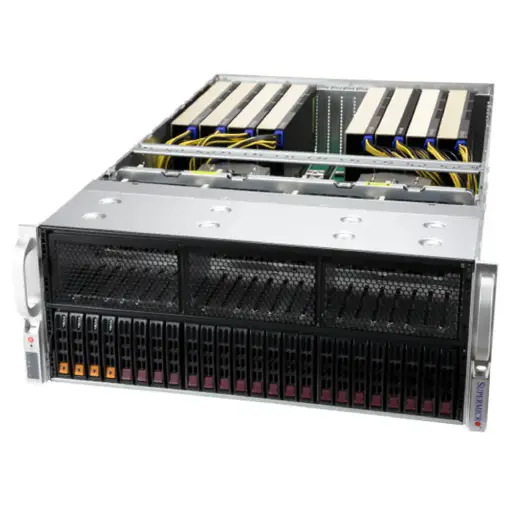 Supermicro AS 4125GS (GPU A+ Server AS -4125GS)
USD72,000
-
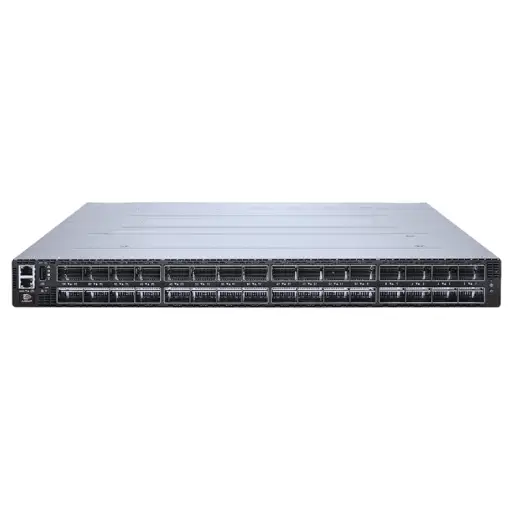 NVIDIA Quantum-2 QM9700
Rated 4.50 out of 5USD33,600
-
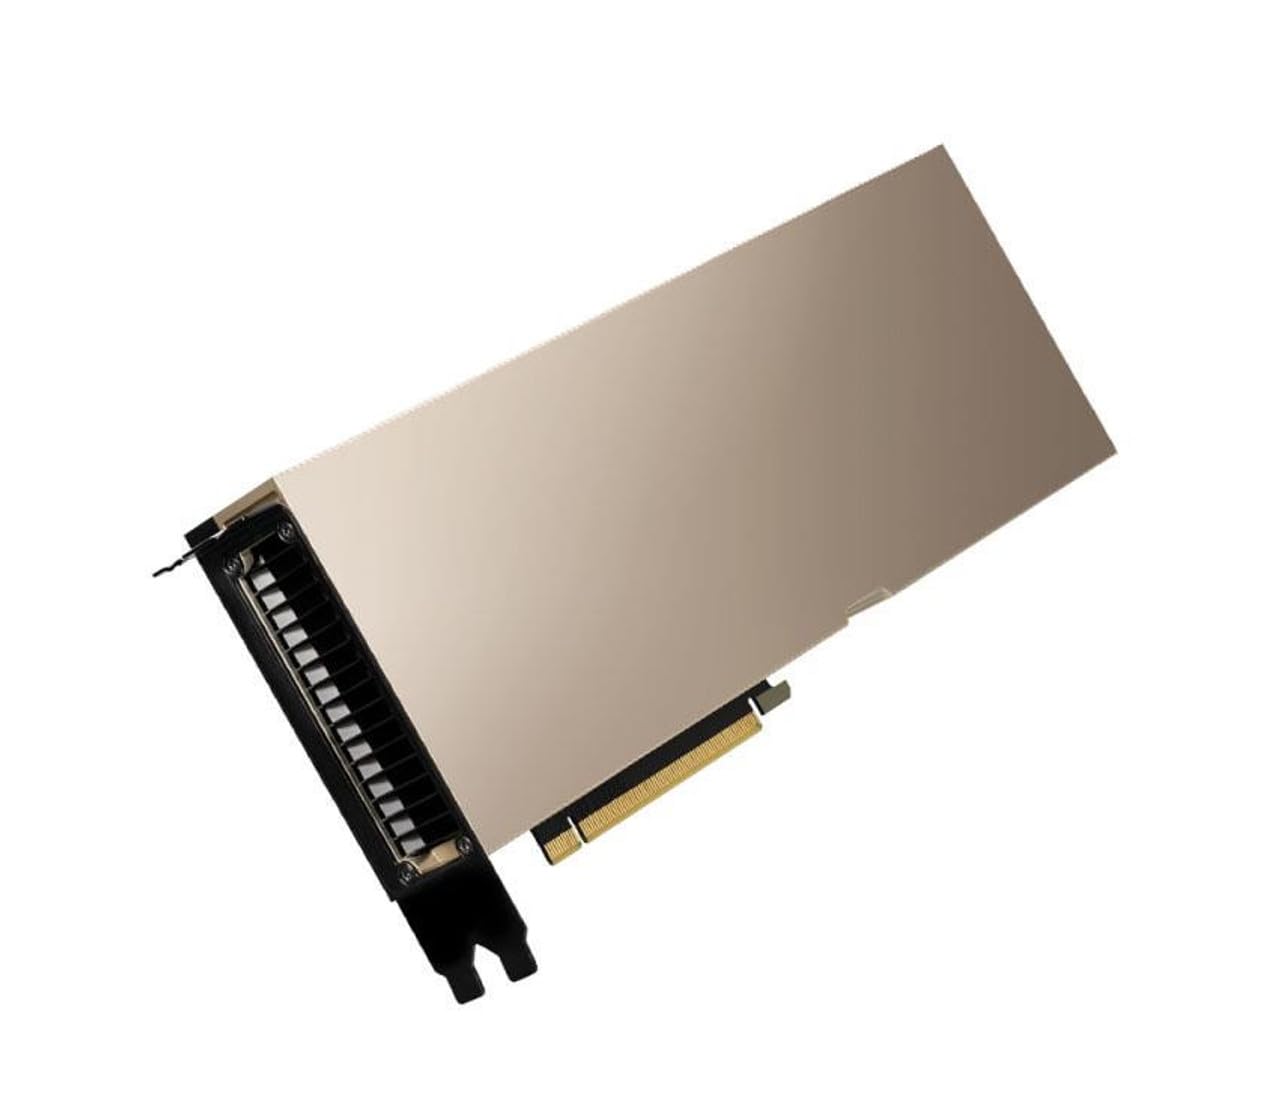 NVIDIA A100 80GB Tensor Core GPU
USD24,000
Best GPUs for Running Local LLMs
A few years ago, running a large language model on your own machine felt like a niche hobby for enthusiasts with oversized hardware budgets. In 2026, it has become a practical decision that companies, developers, and even independent professionals are making on a regular basis.
The reason is straightforward. Cloud-based AI is fast and powerful, but every prompt you send leaves your system. For casual use like asking for recipes, that may not matter. But for law firms handling sensitive contracts, startups working with proprietary code, or clinics processing patient data, it becomes a serious concern. Local LLMs solve this problem by keeping everything on your own hardware — your data stays private, and ongoing subscription costs disappear.
However, there is a catch: the GPU you choose determines the entire experience. Pick the wrong one and you will face slow loading times, low generation speeds, and frequent crashes. Pick the right one and running local models can feel remarkably close to using ChatGPT, with the added benefit that nothing ever leaves your device.
This guide explains which GPUs make sense in 2026 depending on your actual needs.
Why VRAM Is the Most Important Specification
VRAM is the most important factor when choosing a GPU for running large language models.
VRAM is the dedicated memory on your GPU. You can think of it as the workspace where the model lives while it is running. A small workspace can only hold small models, while a larger one allows you to run more capable systems. No matter how powerful your GPU is, if the model does not fit into VRAM, performance becomes unusable.
Here is a rough breakdown for 2026:
- Models with 3B to 7B parameters typically require around 8GB of VRAM. These are suitable for learning and basic applications.
- Models in the 13B to 14B range require approximately 16GB of VRAM and are commonly used by serious everyday users.
- Models between 30B and 34B require about 24GB of VRAM and start to feel suitable for production-level workloads.
- A 70B model — which can reach performance comparable to GPT-4-class systems in many tasks — requires 32GB or more.
- For full-quality 70B models without compression techniques, you are looking at 48GB+ of VRAM.
Other specifications such as memory bandwidth, CUDA cores, and tensor cores are also important, but only after you have enough VRAM. A fast GPU that cannot load the model is essentially useless for this purpose.
A Quick Word on Quantization
Before looking at specific GPUs, you need to understand one key concept called quantization.
A full-precision 70B model requires around 140GB of VRAM, which no consumer GPU can provide. Quantization solves this by compressing the model to make it runnable on smaller hardware.
For example:
- Q4 reduces a 70B model to roughly 40GB, with only a minimal quality loss for most everyday tasks.
- Q5 and Q8 preserve more quality but require more memory.
This technique is what makes running large-scale AI models on consumer-grade gaming GPUs possible. Nearly all benchmarks in this guide assume Q4 quantization, as it is the most practical choice for most users.
The Best GPUs for Local LLMs in 2026
Let’s get to the actual picks. I’ll break this down by what kind of user you are, because there’s no single “best” card — only the best card for what you’re trying to do.
The Sweet Spot for Most People: RTX 5060 Ti (16GB)
If you’re starting out and want to do real work without spending real money, this is the card to buy. The RTX 5060 Ti with 16GB of GDDR7 lands between $429 and $499, runs Qwen 2.5 14B and Llama 3.1 8B comfortably at 30–50 tokens per second, and only pulls about 165 watts.
It won’t run 70B models smoothly, but for the vast majority of developers, content creators, and small teams using local AI as a coding assistant or writing helper, this is more than enough. Low power draw, widely available, and the price-to-VRAM ratio is the best in the lineup.
If you’re reading this guide and thinking “I just want to get started without overthinking it,” buy this one.
The Used-Market King: RTX 4090 (24GB)
The RTX 4090 is no longer new, but on the second-hand market in 2026 it’s quietly become one of the smartest buys for local AI. With 24GB of GDDR6X and prices in the $1,200–$2,000 range (depending on condition), it opens up territory the 5060 Ti can’t reach: 30B models at full speed, and 70B models at Q4 with around 7–9 tokens per second.
The catch is that you’re buying used. Always check warranty, return policy, and the card’s history. It also pulls 450W, so make sure your power supply can handle it.
For research workloads, professional content work, or anyone who needs more VRAM than the 5060 Ti offers without paying flagship prices, the used 4090 is the value play of the year.
The Performance King: RTX 5090 (32GB)
This is the card you buy when you’ve decided to stop compromising. 32GB of GDDR7, 1,792 GB/s of bandwidth, and the only consumer GPU on the market that runs Llama 3.1 70B at Q4 without pushing anything onto the CPU.
Real-world numbers: around 12–15 tokens per second on a 70B Q4 model. That’s roughly one full sentence every two seconds — perfectly usable for daily work. On smaller models, it absolutely flies: 80+ tokens per second on 8B, 50+ on 14B.
Now the downsides. Street prices in 2026 sit somewhere between $2,500 and $4,800 — the global DRAM shortage hasn’t helped. It pulls 575 watts under load, which means about $20–25 a month in electricity if you’re running it heavily. And depending on where you live, finding one at a sane price is still a small adventure.
But if 70B models are part of your workflow, nothing else in the consumer space competes. Buy it once and stop thinking about upgrades for the next two years.
The Quiet Inference Champion: Mac Studio M4 Max (128GB)
Here’s the plot twist a lot of people don’t expect: for pure inference at the 70B tier, the best machine of 2026 might not be a GPU at all. It’s a Mac.
The Mac Studio M4 Max with 128GB of unified memory ($3,499–$3,699 complete) runs Llama 3.3 70B at Q4 at around 8–15 tokens per second. It’s a full computer, not a card you need to build around. It draws a fraction of the power of an RTX 5090. It runs silently. And it has more usable memory for AI than any single consumer NVIDIA card you can buy.
The downside? No CUDA. If your workflow depends on training, fine-tuning, or any of the dozens of tools built around NVIDIA’s ecosystem, this isn’t your machine. Apple Silicon shines at running models, not training them.
But if you just want a quiet, always-on local AI box that handles 70B beautifully — this is the most boring, reliable answer in 2026.
The Professional Tier: RTX PRO 6000 (96GB)
This is where things get serious. The RTX PRO 6000 Blackwell Workstation Edition packs 96GB of GDDR7 at 1.8 TB/s — nearly the bandwidth of an RTX 5090, with three times the memory.
It fits a 70B model in Q4 with 50GB of headroom to spare. That headroom is what makes it special: you can serve four or five concurrent users through vLLM, handle long-context workloads, or load multiple models at once without juggling.
The price tag is the reality check. A complete professional workstation built around a single PRO 6000 runs around $22,000. A dual-GPU setup pushes $30,000+. At that level, the honest comparison isn’t “which card is best” — it’s “should I just rent a B200 in the cloud for a year instead?”
For most people, the answer is cloud. For teams with always-on local CUDA needs, strict data residency rules, or compliance constraints that rule out the cloud entirely, this is the only sensible local option.
Honorable Mentions
A few cards worth knowing about, even if they’re not the main recommendation.
The RTX 5080 (16GB) has faster compute than the 4090 but the same VRAM as the 5060 Ti. It’s a great gaming card, but for AI specifically, the 5060 Ti gives you the same memory at a much lower price. Skip it.
The AMD Radeon RX 7900 XTX (24GB) offers more VRAM per dollar than NVIDIA, but ROCm — AMD’s CUDA alternative — is still rough around the edges in 2026. It works for inference through llama.cpp, but expect to spend time debugging instead of training. Recommended only if you genuinely prefer AMD and don’t mind tinkering.
The AMD Strix Halo mini PCs with 128GB of unified memory at around $2,000 are an interesting curveball. Dense 70B models run slowly (3–5 tokens/sec), but MoE models like Llama 4 Scout do much better (10–20 tokens/sec). If your workloads are MoE-heavy and budget is tight, this is worth a look.
The NVIDIA DGX Spark at $4,699 with 128GB sounds compelling on paper, but for inference a Mac Studio is twice as fast at lower cost, and for training the cloud is cheaper. Hard to recommend unless you specifically need always-on local CUDA at 128GB.
How to Match a Card to Your Actual Use Case
Specs are nice, but reality is messier. In practice, GPU choice depends less on benchmarks and more on how you actually plan to use local models.
If you are a beginner just exploring local AI, the RTX 5060 Ti is usually enough. At this stage, the bottleneck is rarely hardware. It is learning how the tools and workflows fit together.
If you are a developer or solo founder building features on top of local LLMs, the RTX 5060 Ti still works, but a used RTX 4090 is often the point where things become noticeably easier. It gives you enough headroom to realistically work with 30B models without constant compromises.
If you are a researcher or part of a content team working with large models, the RTX 5090 is where consumer hardware starts to feel serious. It is one of the few options that can handle 70B-class models at usable speeds without immediately hitting limits.
If you are part of an ML team or a company serving multiple users, consumer GPUs are usually no longer the right tool. At that point, the RTX PRO 6000 becomes relevant, or in many cases cloud hardware like the B200 is the more practical option, with local machines used mainly for development and testing.
If you want a quiet, always-on inference setup that runs without the noise and power draw of high-end GPUs, the Mac Studio with M4 Max is often the most balanced choice.
Don’t Forget the Rest of the System
A GPU isn’t a computer. Every NVIDIA recommendation in this guide assumes a workstation built around it. For an RTX 5090, expect a complete system to land between $5,000 and $8,000. For dual-GPU builds, $9,000 to $12,000. The card alone is only half the story.
A few things that often get overlooked: you need a power supply rated well above the GPU’s TDP (1,500W or more for dual 5090s), good cooling because these cards run hot, and enough fast storage to hold multiple models — 1TB of NVMe is the practical minimum, 2TB is more comfortable.
Electricity costs are also real. An RTX 5090 running 8 hours a day adds about $20–25 to your monthly bill. A 5060 Ti closer to $6. Not enormous, but worth knowing.
What Software Should You Run?
The hardware does the math. The software is where you actually live. Three tools dominate local AI in 2026, and picking the right one saves you days of setup.
Ollama is the easiest place to start. One command installs it, one downloads a model, and it runs in the background with a built-in API. Pair it with Open WebUI and you have a private, ChatGPT-style chat interface running entirely on your own machine. Most people should start here.
LM Studio is a full desktop app with a graphical interface — no terminal required. Great for non-technical users and Mac fans who prefer clicking over typing.
llama.cpp is the bare-metal option. No GUI, all command line, but the fastest of the three and the most flexible for stretching VRAM across CPU and GPU. If you’re a power user or running production inference, this is the move.
For most readers: start with Ollama, upgrade to llama.cpp when you hit a limitation.
What’s Coming Next
A quick look at what’s on the horizon, because hardware buying always has a “should I wait?” question hanging over it.
The Mac Studio M5 Ultra is expected mid-2026, potentially with 1,200+ GB/s of bandwidth and up to 256GB of memory. If you can wait two or three months and you’re in the Apple camp, wait.
The RTX 5090 Super with 48GB of GDDR7 has been rumored, but the ongoing DRAM shortage makes a 2026 launch unlikely. Don’t hold your breath.
Models are getting bigger. 70B is the new normal. 200B-class models are already emerging. If you’re buying with 2027 in mind, push toward 32GB of VRAM minimum. A 16GB card is great for 2026 but might start feeling tight by next year.
The Bottom Line
You don’t need to overthink this. Most people buying a GPU for local LLMs in 2026 fall into one of three groups.
If you’re starting out or building a personal coding assistant, get the RTX 5060 Ti. It’s the best $500 you can spend on AI hardware right now.
If you need more headroom — bigger models, serious work, multiple concurrent tasks — get the RTX 5090 or, if you want a quiet all-in-one machine, the Mac Studio M4 Max.
If you’re running a team or a business that depends on local AI being always-on with multiple users, you’re either looking at the RTX PRO 6000 or making peace with the cloud.
The truth is that 2026 is the first year where running serious AI privately, on your own hardware, isn’t just possible — it’s practical. The tools are mature, the models are good enough, and the GPUs finally have enough memory to make it all work. Whatever you buy, you’re walking into a year where the gap between local and cloud AI is the smallest it’s ever been. And it’s only going to close further.
Last update at December 2025