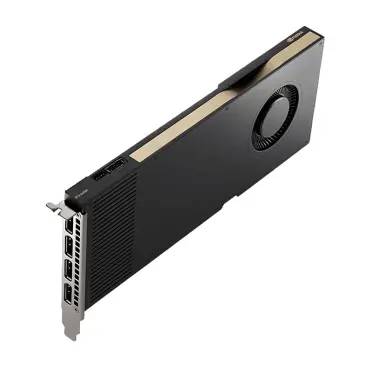
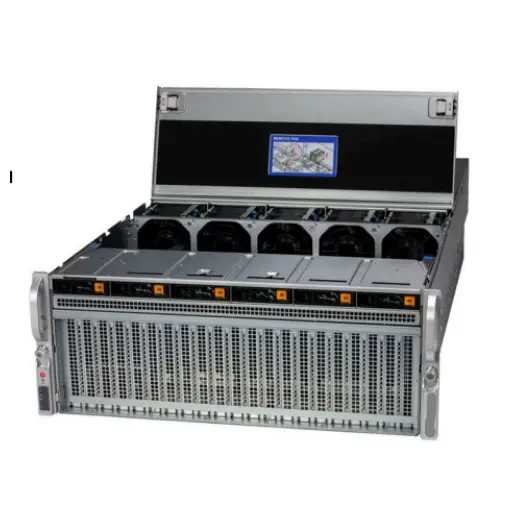
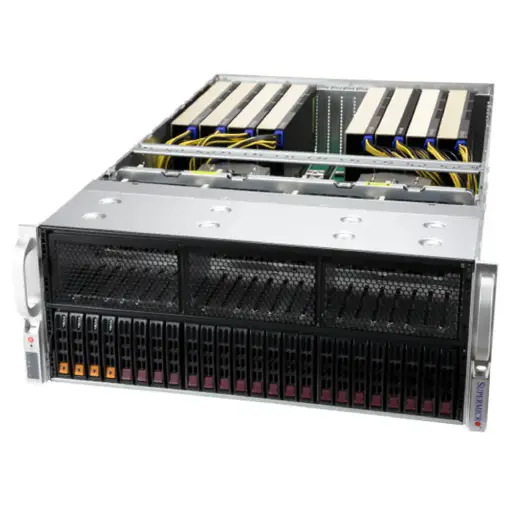
Products Mentioned in This Article

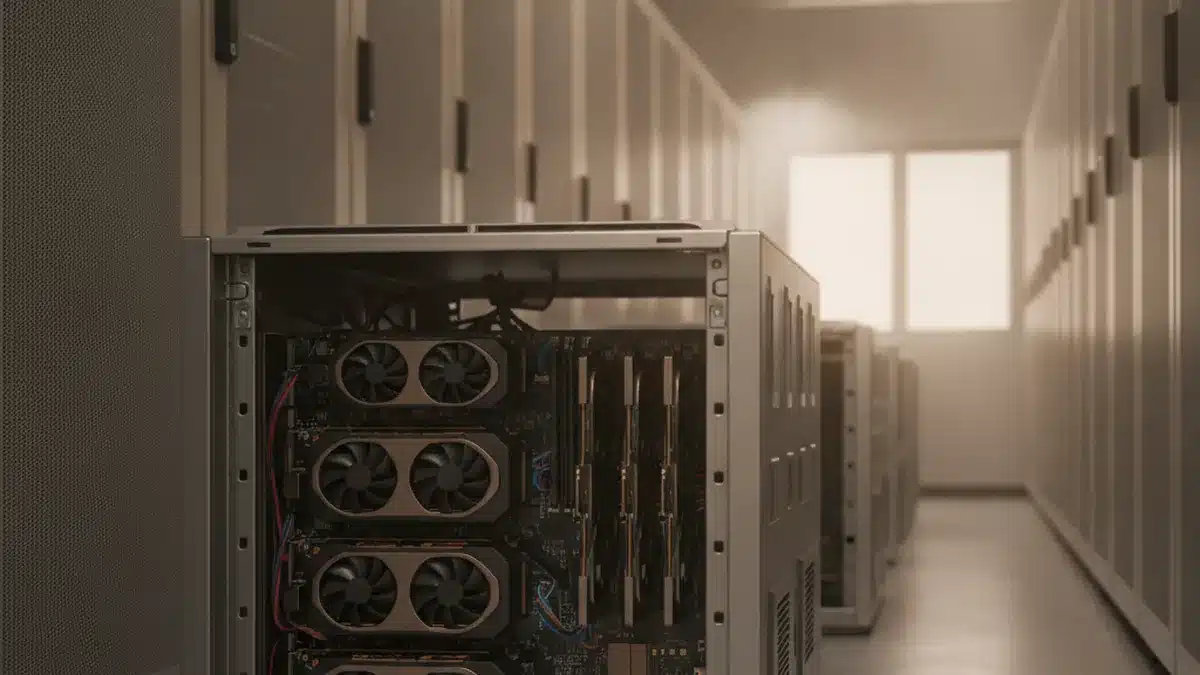
An 8-GPU HGX H100 or H200 server is the reference platform for serious AI work, but for most small and mid-sized businesses it is the wrong purchase. It costs as much as a small office building, needs 10 kW or more per server, and its NVLink fabric only pays off for large-scale training. Most SMBs actually need to run inference on open models, fine-tune with LoRA, or serve internal assistants and RAG systems. For those workloads, PCIe GPU servers built around the L40S, H100 NVL or RTX PRO 6000 Blackwell deliver most of the value at a fraction of the cost and power. This guide compares the main alternatives and shows which one fits which workload.
Why HGX is overkill for most SMBs
- Cost: an 8-GPU HGX system is a multi-hundred-thousand-dollar purchase before networking and storage; see our 8-GPU H100 server cost breakdown.
- Power and cooling: 10 kW+ per server exceeds what many office server rooms and colocation racks can supply.
- NVLink benefits: the NVSwitch fabric matters most for training large models across all eight GPUs. Inference of models that fit on one or two GPUs gains little.
- Utilisation: SMB workloads often leave expensive GPUs idle most of the day.
The main alternatives
| GPU | Memory | Strengths | Limits |
|---|---|---|---|
| NVIDIA L40S | 48 GB GDDR6 ECC | Strong FP8 inference, graphics and video AI, lower power (~350 W), good availability | Lower memory bandwidth than HBM; no NVLink |
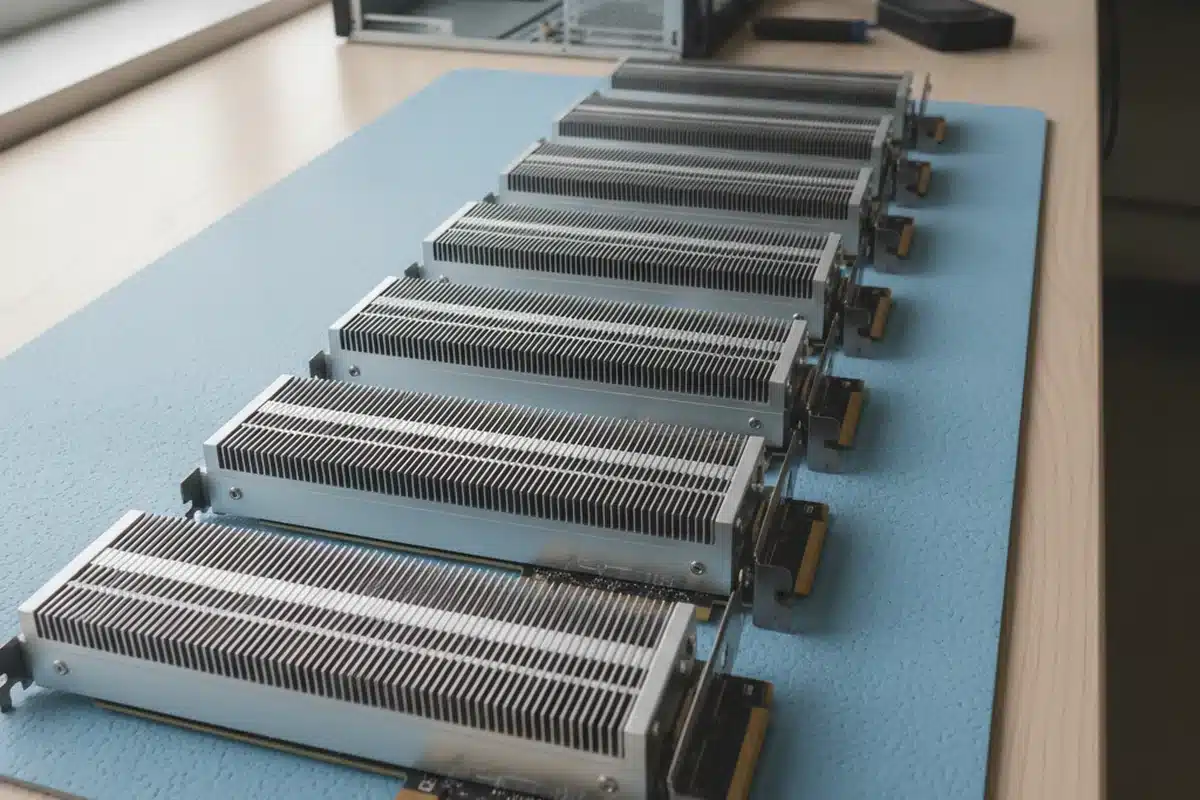
| H100 NVL (PCIe) | 94 GB HBM3 | Hopper performance in standard servers; NVLink bridge between card pairs | Higher price; ~350–400 W per card; passive cooling needs strong airflow |
| RTX PRO 6000 Blackwell Server Edition | 96 GB GDDR7 ECC | Large memory per card, FP4/FP8 support, strong value for inference and mixed AI/graphics | No NVLink; up to ~600 W per card |
| H200 NVL (PCIe) | 141 GB HBM3e | Largest memory and bandwidth in PCIe form, fits bigger models on fewer cards | Premium price |
Matching the platform to the workload
| Workload | Recommended setup |
|---|---|
| Internal chatbot / RAG on 8–14B models, dozens of users | 1–2 × L40S in a 2U server |
| 70B model in FP8 for a team | 2 × RTX PRO 6000 Blackwell (192 GB) or 2 × H100 NVL with NVLink bridge |
| Long-context or high-concurrency serving of 70B models | 4 × RTX PRO 6000 or 2–4 × H200 NVL |
| LoRA / QLoRA fine-tuning up to 70B | 1–2 × H100 NVL or RTX PRO 6000 |
| Computer vision and video analytics | L40S (video encoders and good FP8) |
| Full pre-training or full fine-tuning of large models | HGX remains the right choice |
Size memory for your models with our LLM GPU memory guide, and compare inference throughput in best GPU for LLM inference.
Server platforms for PCIe GPUs
- 2U servers with 2–4 GPUs: good for L40S and inference nodes; check PSU capacity and airflow for passive cards.
- 4U servers with 4–8 double-width GPUs: such as the HPE DL380a Gen12 or Supermicro GPU servers; suitable for RTX PRO 6000 and H100/H200 NVL.
- Workstations: for development teams, a tower with one or two RTX PRO cards may be enough.
Cost and power comparison (indicative)
| Configuration | Total GPU memory | Typical power | Relative cost |
|---|---|---|---|
| 2 × L40S server | 96 GB | ~1.5 kW | Low |
| 4 × RTX PRO 6000 server | 384 GB | ~3–3.5 kW | Medium |
| 4 × H100 NVL server | 376 GB | ~2.5–3 kW | Medium–high |
| 8 × H100 HGX | 640 GB | ~10 kW | Very high |
Prices move quickly; for current figures see H100, H200 and B200 prices, or ask ITCT for a quote on available Dubai stock.
When HGX is still worth it
- You train or fully fine-tune large models regularly.
- You need tensor parallelism across eight GPUs with maximum bandwidth.
- You run a GPU cloud or shared platform with high utilisation.
For everyone else, a PCIe GPU server is usually the smarter first step, and it can be added to later as workloads grow.
Frequently asked questions
What is the best alternative to an HGX H100 for inference?
For most SMB inference, PCIe servers with RTX PRO 6000 Blackwell or H100 NVL cards. For smaller models and video AI, L40S offers the best value.
Is the L40S good for LLMs?
Yes for models up to about 30B parameters, or larger models quantised to 4-bit. Its GDDR6 bandwidth is lower than HBM, so token speed on large models is below H100.
Do I need NVLink for inference?
Not usually. If a model fits on one or two GPUs, PCIe is sufficient. NVLink helps when splitting one large model across several GPUs or for training.
RTX PRO 6000 Blackwell or H100 NVL?
RTX PRO 6000 offers more memory per card and better value for inference; H100 NVL offers higher memory bandwidth, NVLink between pairs and a mature data center ecosystem.
How much power does a 4-GPU server need?
Roughly 2.5 to 3.5 kW depending on the GPUs, plus cooling. Check rack power and PSU redundancy before ordering.
Last update at December 2025